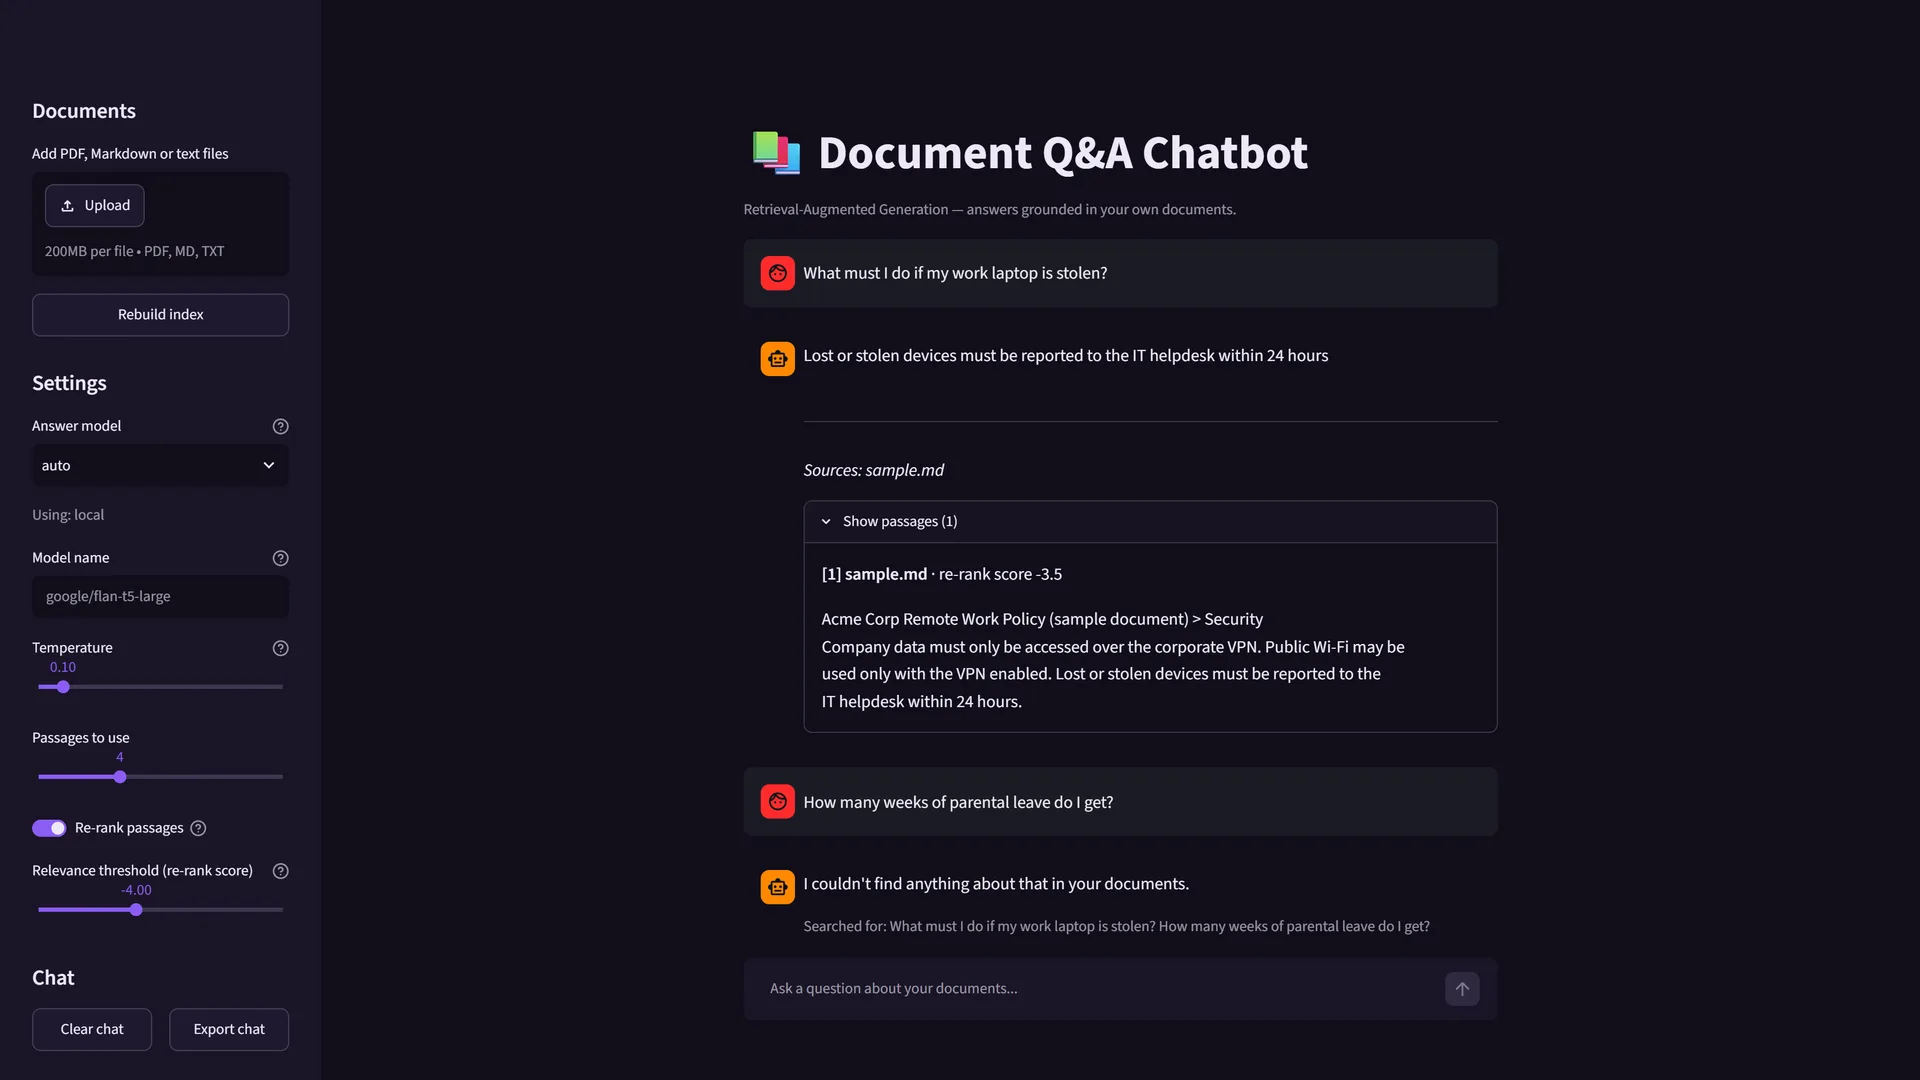
The Document Q&A Chatbot web app. Asked what to do if a work laptop is stolen, it answers that lost or stolen devices must be reported to the IT helpdesk within 24 hours and shows the source passage from sample.md. Asked how many weeks of parental leave, it replies that it couldn't find anything about that in the documents. The sidebar holds upload, rebuild index, answer model, temperature, passages and relevance threshold settings.
completed

Document Q&A Digital Assistant (RAG)

A retrieval-augmented assistant that answers questions about your own PDFs and notes from the passages it retrieves, cites them, and refuses to guess. Evaluated on 1,000 SQuAD 2.0 questions.

  • Right passage ranked 1st for 88%
  • Refuses 93% of off-topic questions
  • 3 bugs found by its own evaluation

Python · sentence-transformers · FAISS · BM25 · cross-encoder re-ranking · Streamlit · Claude API · OpenAI API · Ollama · FLAN-T5 · pytest · matplotlib

  • #genai
  • #rag
  • #llm
  • #nlp
  • #evaluation
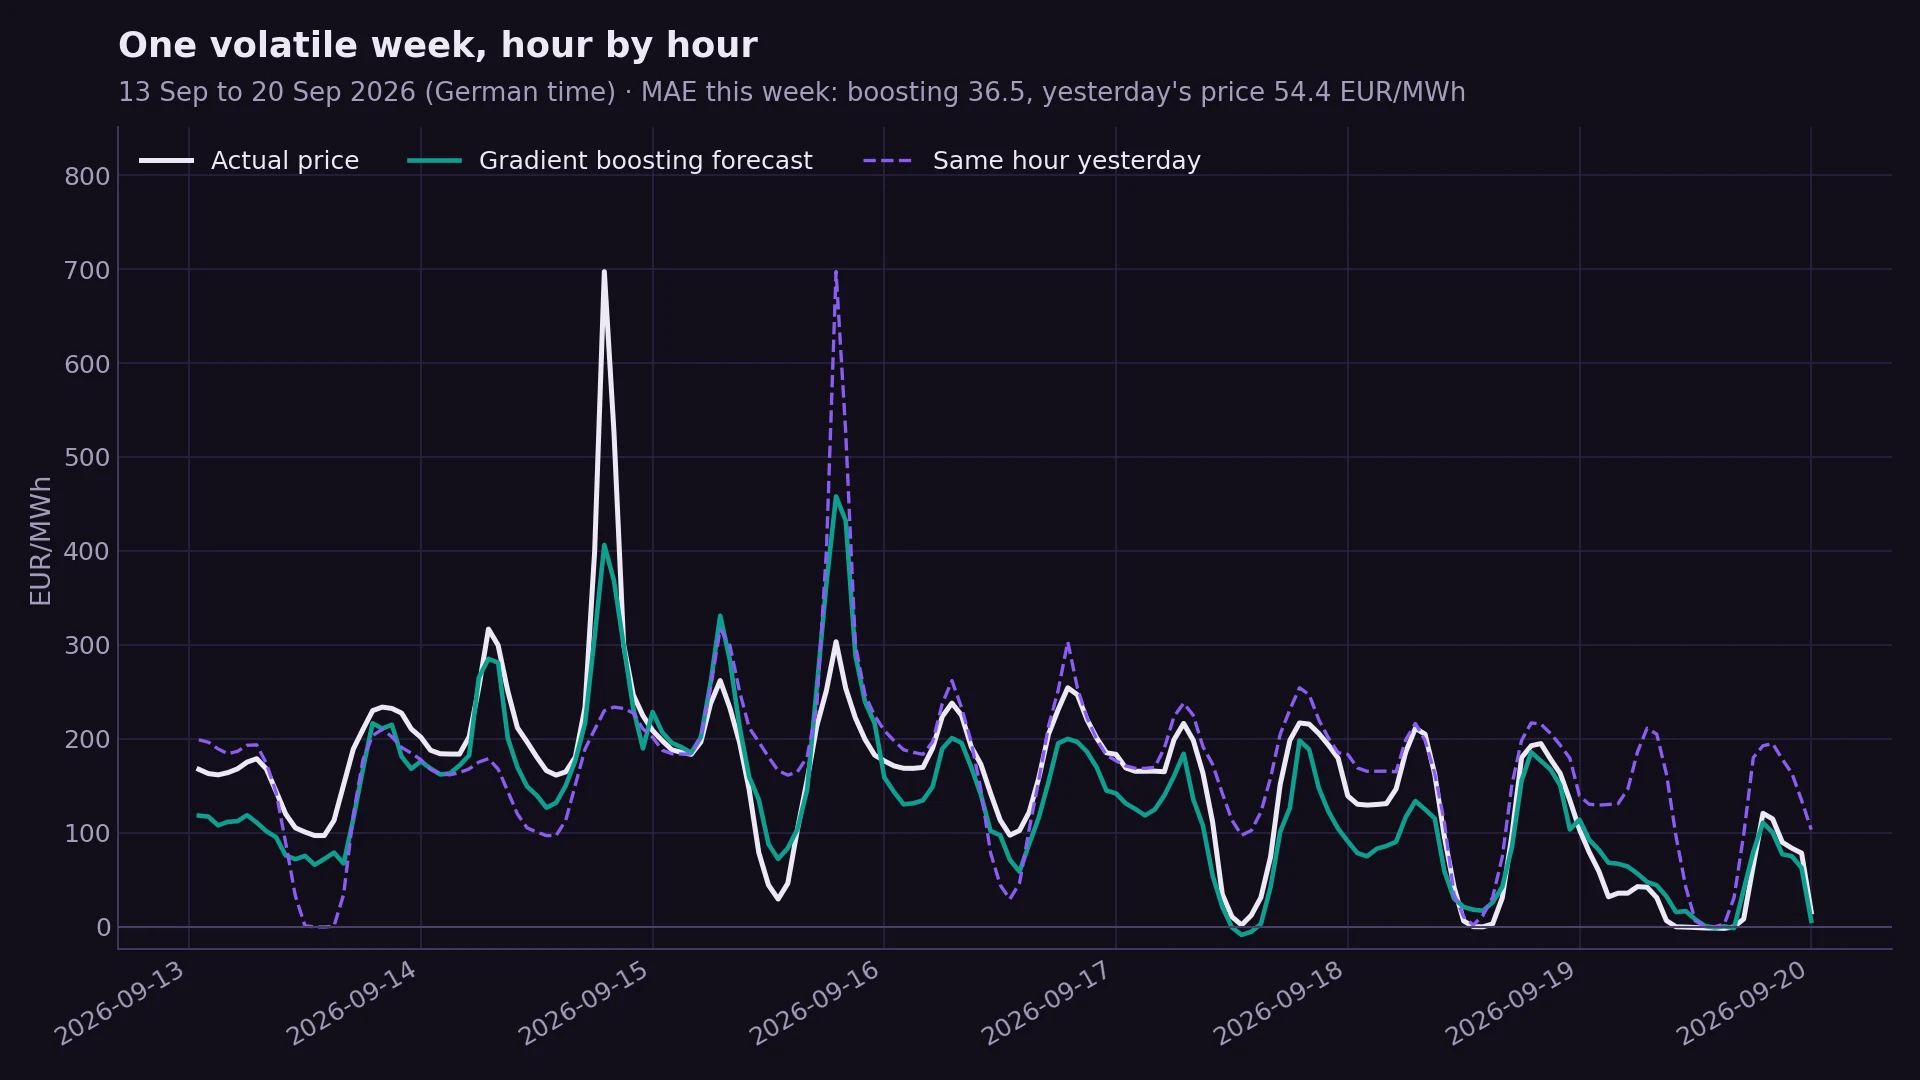
Line chart of one volatile week in September 2026: the actual hourly price, the gradient-boosting forecast and yesterday's price. The forecast follows the daily cycle and most spikes; its error that week was 36.5 EUR/MWh against 54.4 for yesterday's price.
completed

German Electricity Price Forecasting

Forecasting tomorrow's hourly electricity price for Germany from public SMARD data, with auction-safe features and a year-long rolling backtest: 26% lower error than the standard naive forecast.

  • 26% lower error than naive
  • 8,712-hour rolling backtest
  • Leakage-tested features

Python · pandas · scikit-learn · SMARD API · matplotlib · pytest

  • #energy
  • #time-series
  • #forecasting
  • #machine-learning
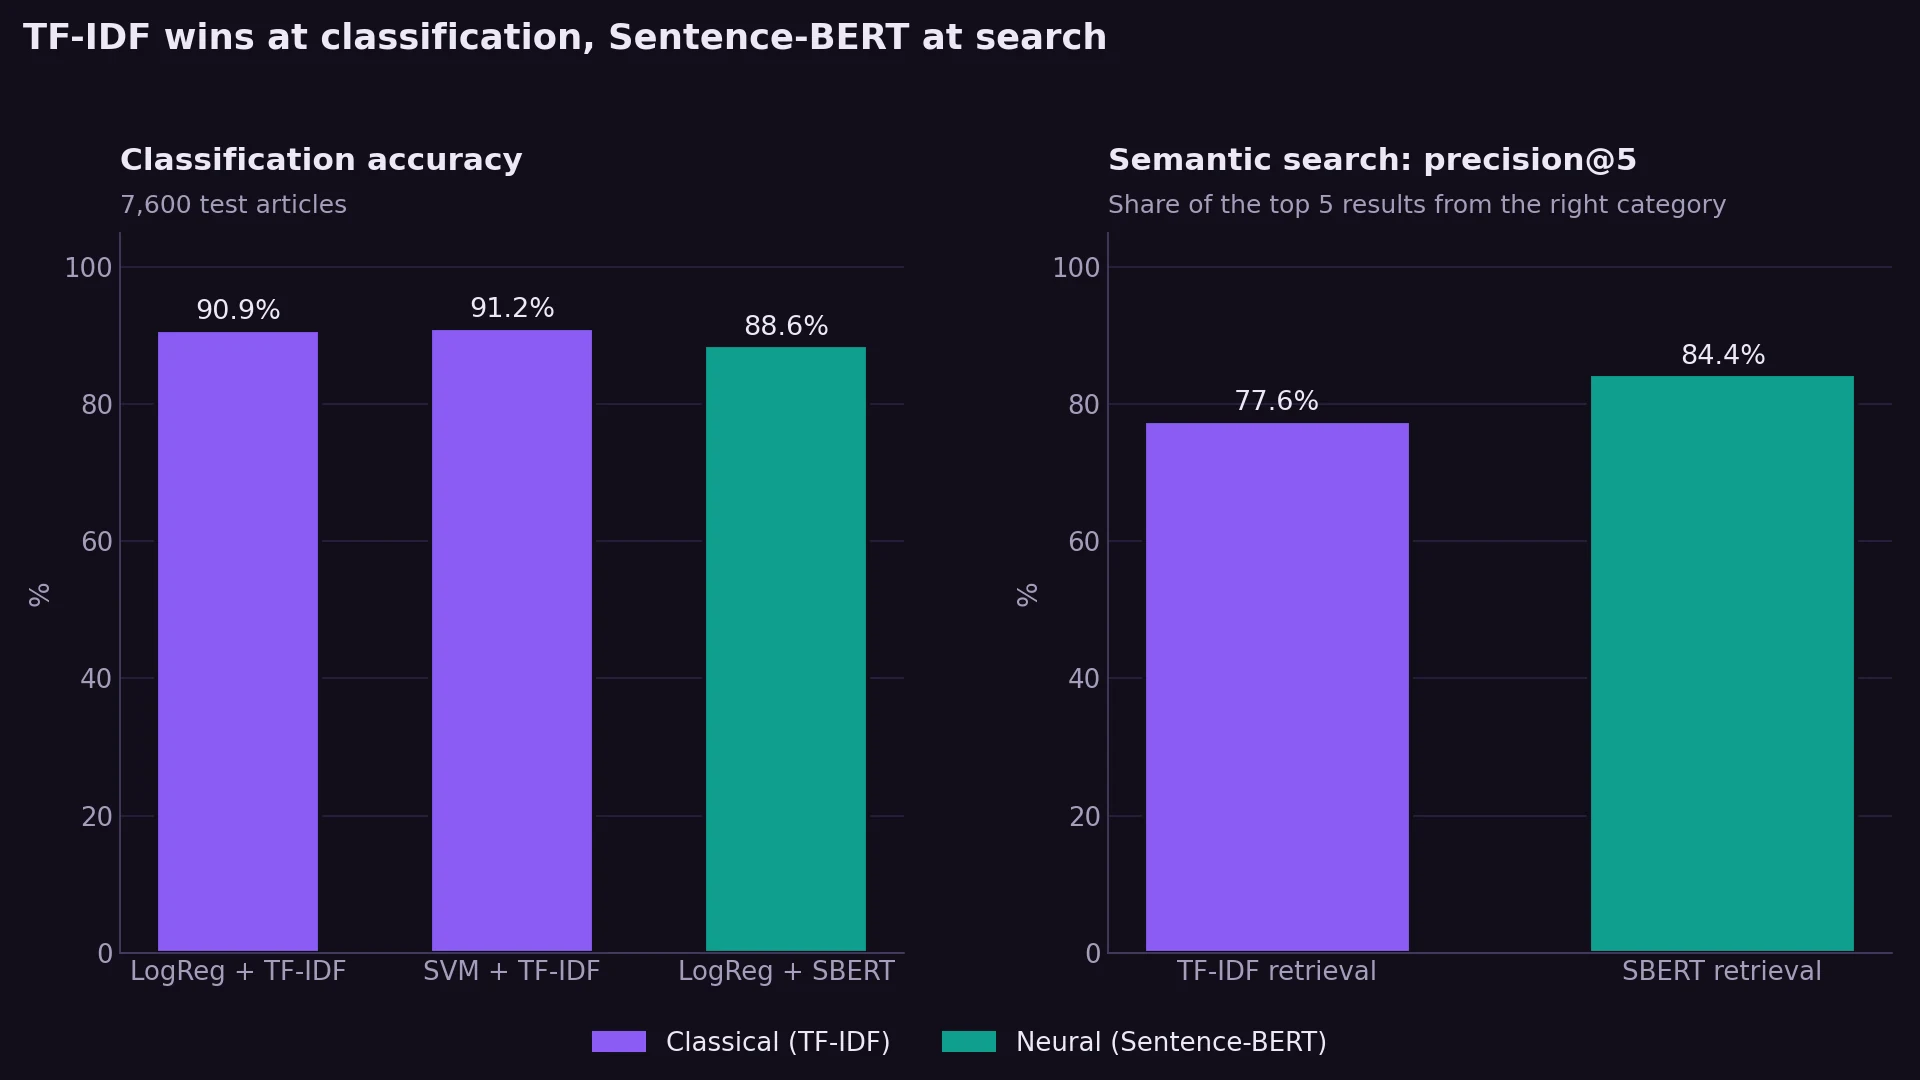
Two bar charts: TF-IDF models reach 90.9 to 91.2% classification accuracy against 88.6% for Sentence-BERT, while Sentence-BERT search reaches 84.4% precision at 5 against 77.6% for TF-IDF.
completed

NLP News Intelligence

Classical ML, Sentence-BERT embeddings and LDA compared on 127,600 AG News articles for classification, semantic search and topic discovery.

  • 91.2% test accuracy
  • P@5 0.844 semantic search
  • Labels recovered by LDA

Python · scikit-learn · sentence-transformers · gensim · spaCy · NLTK · pandas

  • #nlp
  • #machine-learning
  • #semantic-search
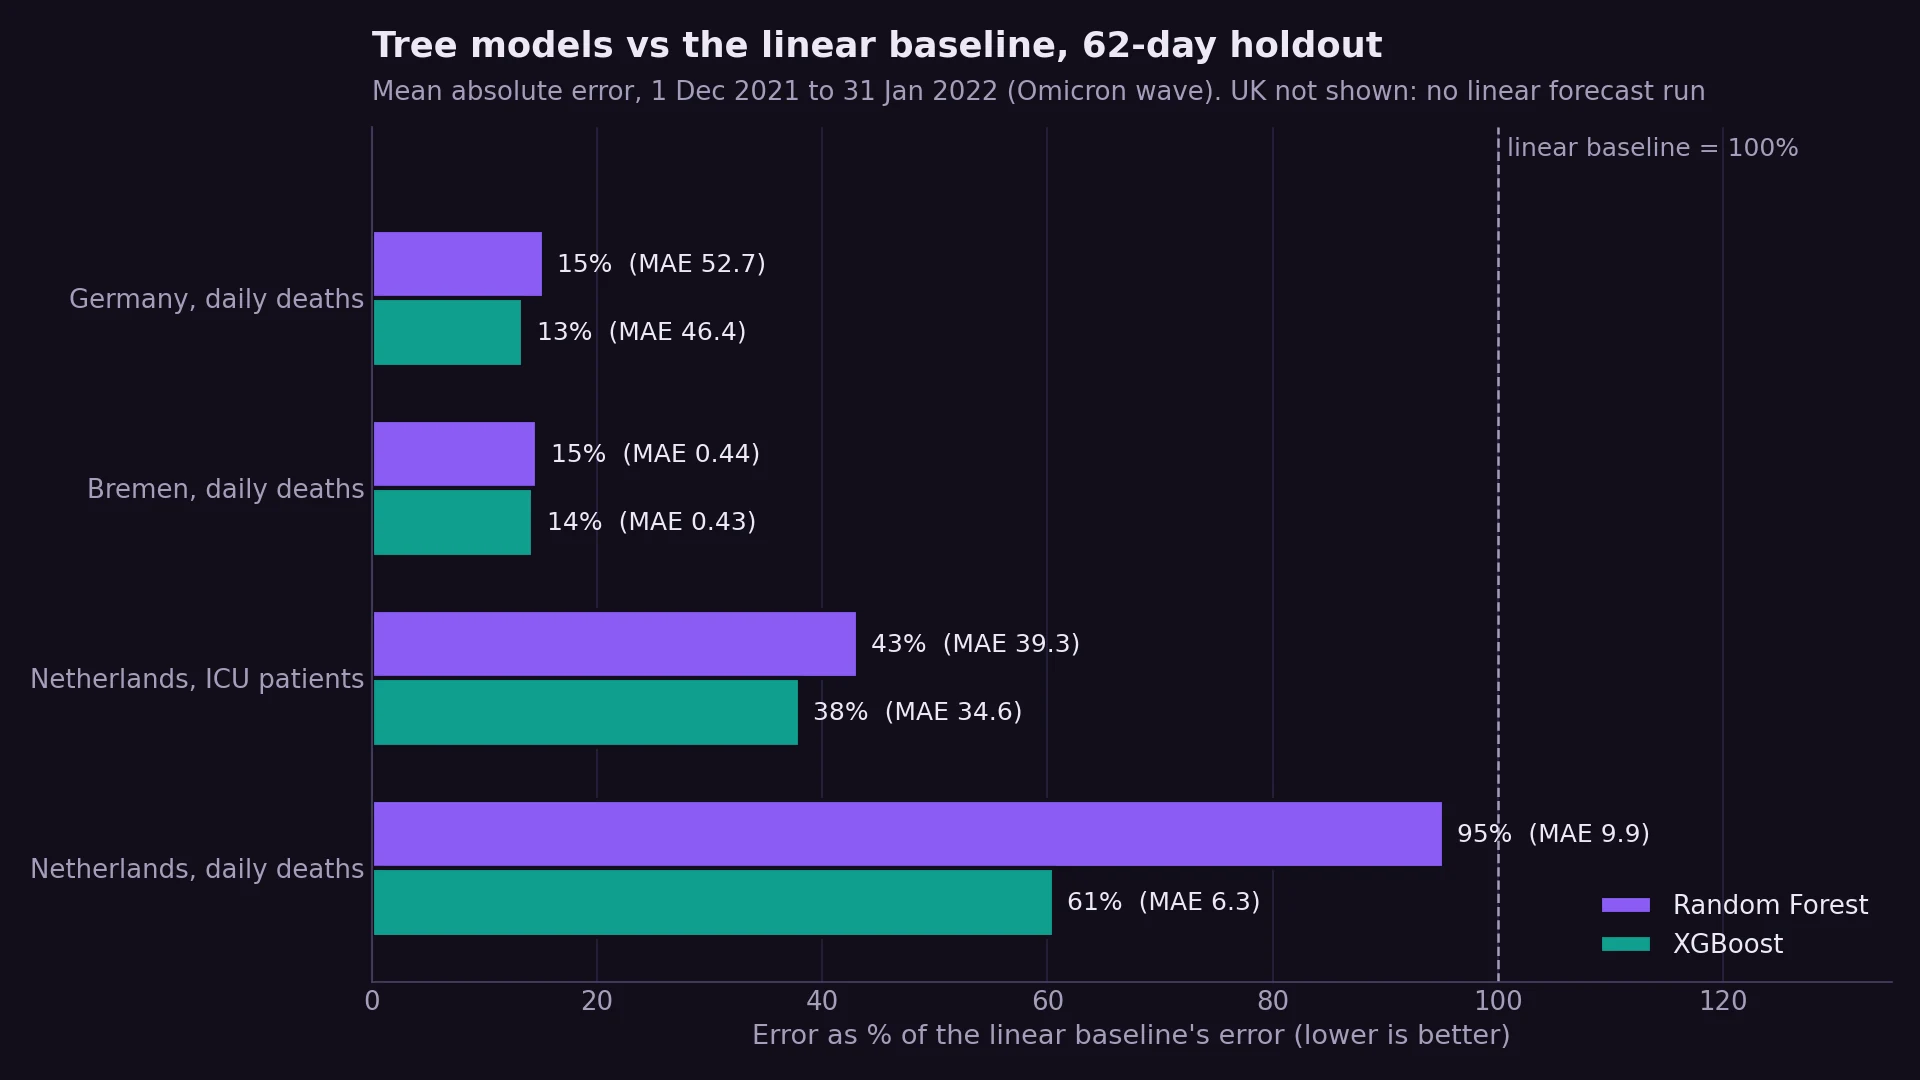
Bar chart comparing Random Forest and XGBoost errors with the linear baseline for four forecasting targets; the tree models' errors are 13% to 95% of the baseline's.
completed

ICU & Mortality Forecasting (COVID-19)

Forecasting COVID-19 ICU occupancy and deaths for the Netherlands, Germany, Bremen and the UK, comparing linear, Random Forest and XGBoost models with time-series backtesting.

  • −87% MAE vs linear baseline
  • 4 regions, 62-day holdouts
  • Time-series CV

Python · pandas · scikit-learn · XGBoost · matplotlib · seaborn

  • #health-tech
  • #time-series
  • #forecasting
  • #machine-learning
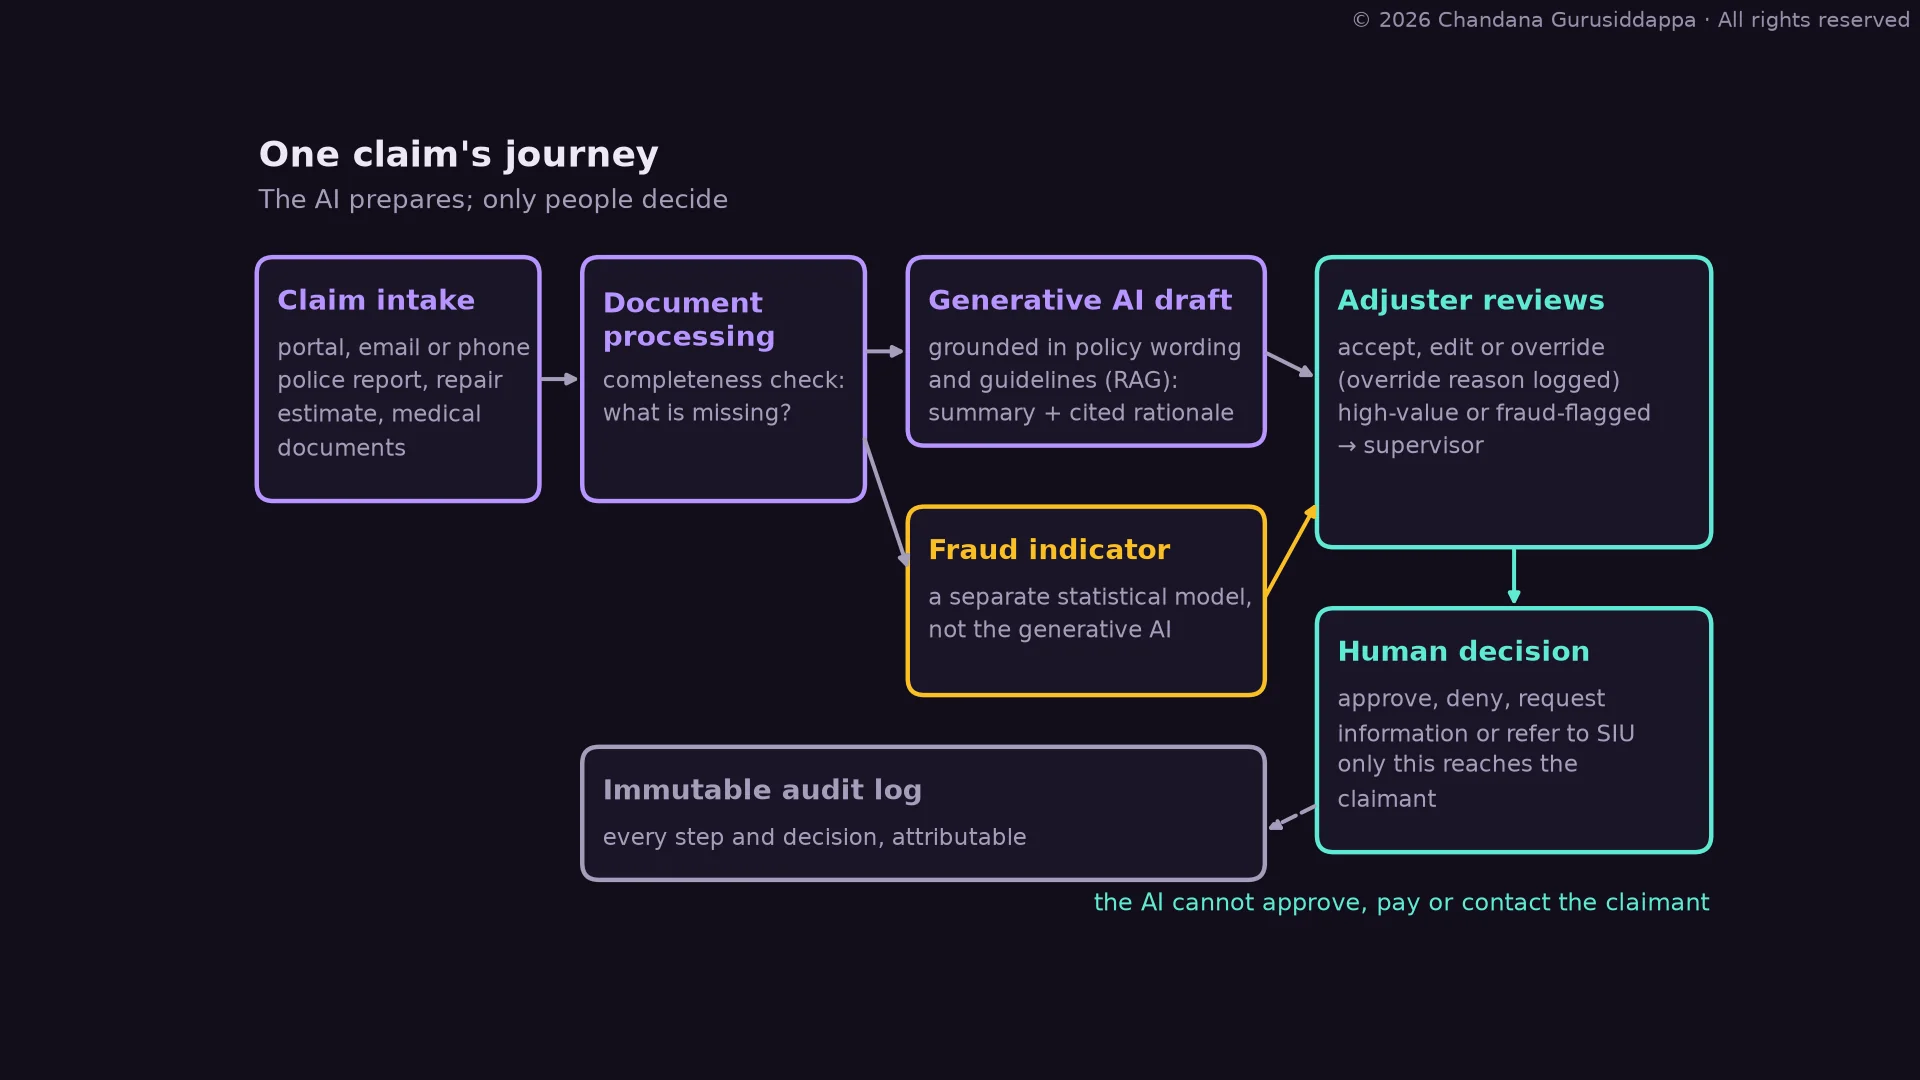
Diagram of one claim's journey. Claim intake and document processing feed a generative AI draft grounded in the policy wording and a separate statistical fraud indicator. An adjuster accepts, edits or overrides the draft, with high-value or fraud-flagged claims going to a supervisor. Only the human decision reaches the claimant, and every step is written to an immutable audit log. The AI cannot approve, pay or contact the claimant.
completed

Claims Copilot: Responsible Generative AI for Motor Insurance

Should a generative-AI copilot be trusted with motor insurance claims? A Responsible AI assessment through five ethical lenses, the EU AI Act and GDPR, risk and governance, backed by a fairness audit and an automation-bias simulation.

  • Five ethical lenses, one verdict
  • Hidden proxy bias: 1.36× (synthetic)
  • Override rate misses harm (ρ = −0.02)

Python · NumPy · SciPy · scikit-learn · matplotlib

  • #responsible-ai
  • #ai-ethics
  • #fairness
  • #ai-governance
  • #insurance
  • #genai
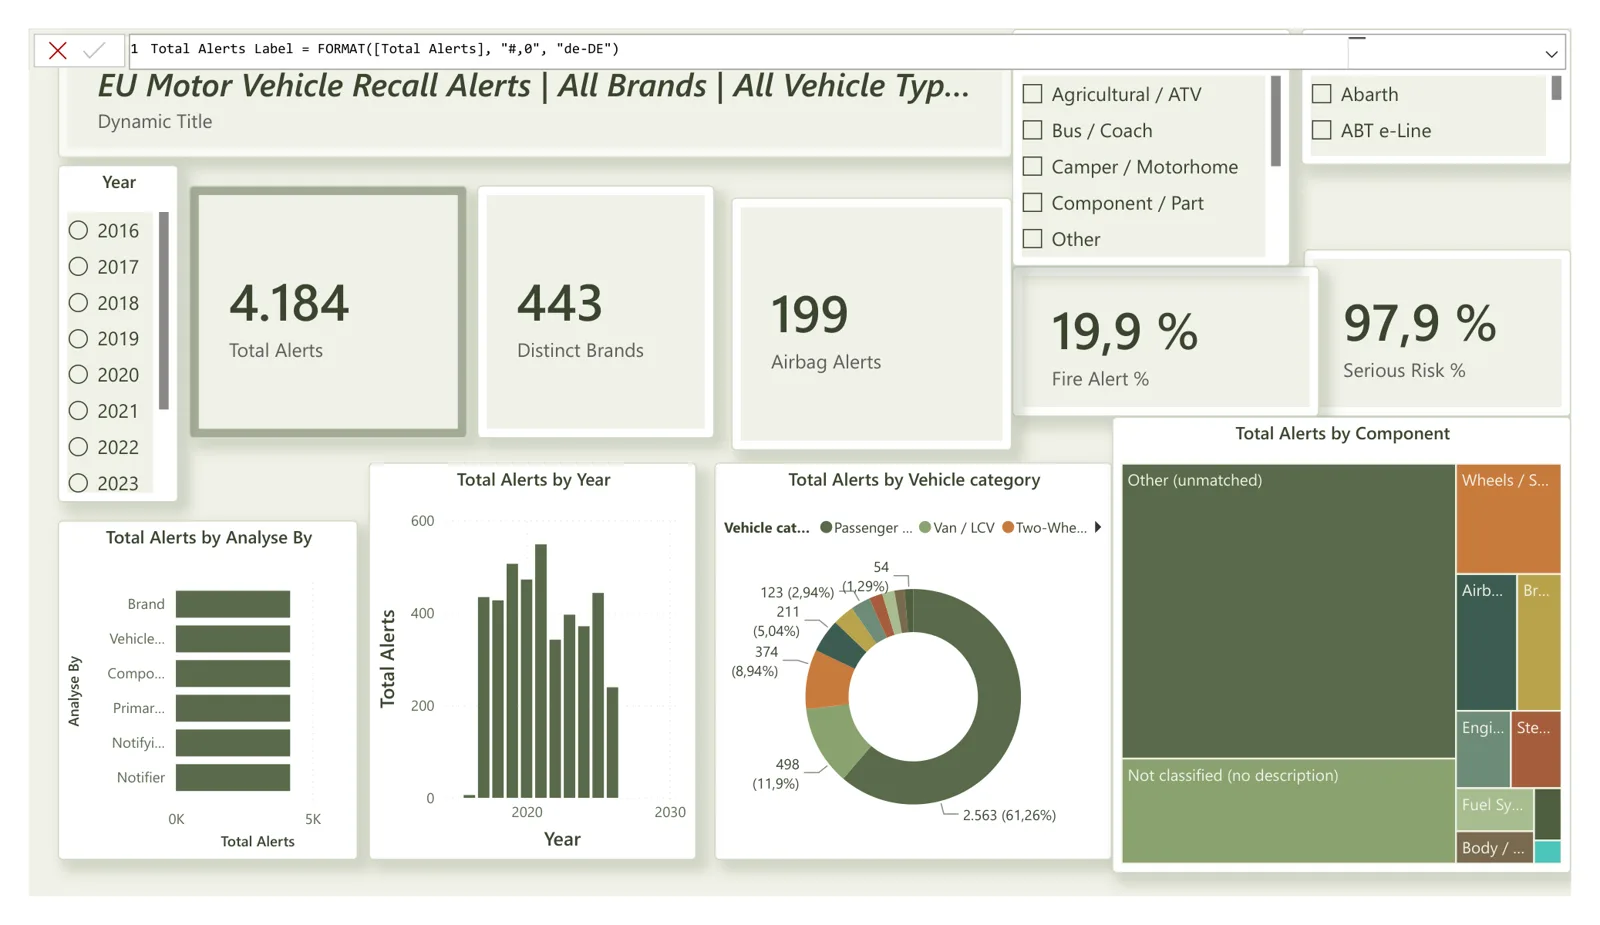
Overview page of the Power BI dashboard: KPI cards for 4,184 alerts, 443 brands, 199 airbag alerts, 19.9% fire alerts and 97.9% serious risk, a column chart of alerts per year from 2016 to 2026, a donut of alerts by vehicle category, and a treemap of alerts by defective component.
completed

EU Safety Gate Motor Vehicle Recalls Dashboard

A Power BI dashboard on 4,184 motor-vehicle recall alerts from the EU Safety Gate system (2016–2026): brands, components, hazards and countries, with every headline card checked against an independent Python recount.

  • 4,184 alerts, 2016–2026
  • Cards match Python recount
  • 9 data issues found and fixed

Power BI · Power Query (M) · DAX · Python · pandas

  • #bi
  • #dashboard
  • #automotive
  • #data-quality
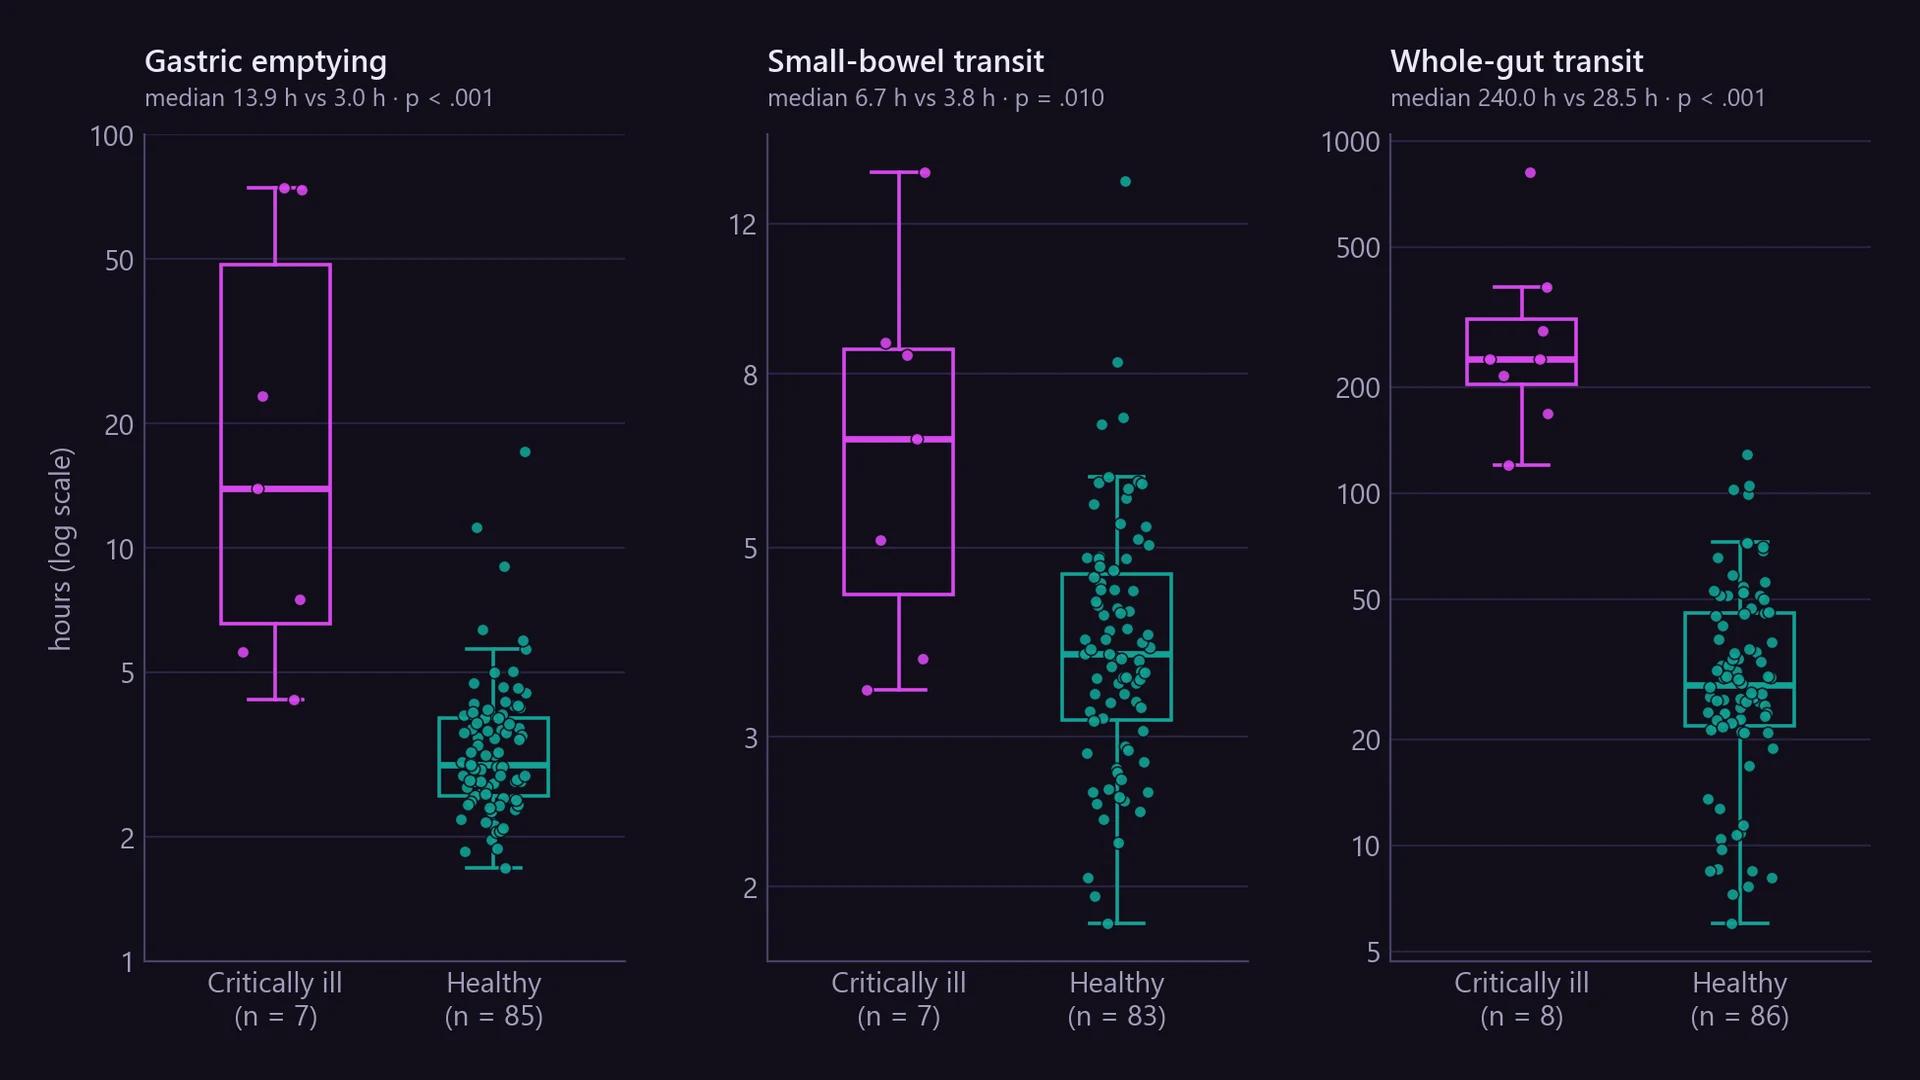
Box plots on a log scale comparing critically ill patients and healthy volunteers. Median gastric emptying is 13.9 vs 3.0 hours, small-bowel transit 6.7 vs 3.8 hours and whole-gut transit 240 vs 28.5 hours; all three differences are significant.
completed

Gut Transit in ICU Trauma Patients (Biostatistics)

A statistical replication of Rauch et al. (2012): do ventilated trauma patients digest more slowly? SmartPill capsule data from 8 ICU patients and 87 healthy volunteers, re-analysed in JASP and Python.

  • Gastric emptying 4.5× slower
  • Mann–Whitney p < .001
  • Pearson vs Spearman flips a result

Python · pandas · SciPy · statsmodels · matplotlib · seaborn · JASP

  • #health-tech
  • #statistics
  • #hypothesis-testing
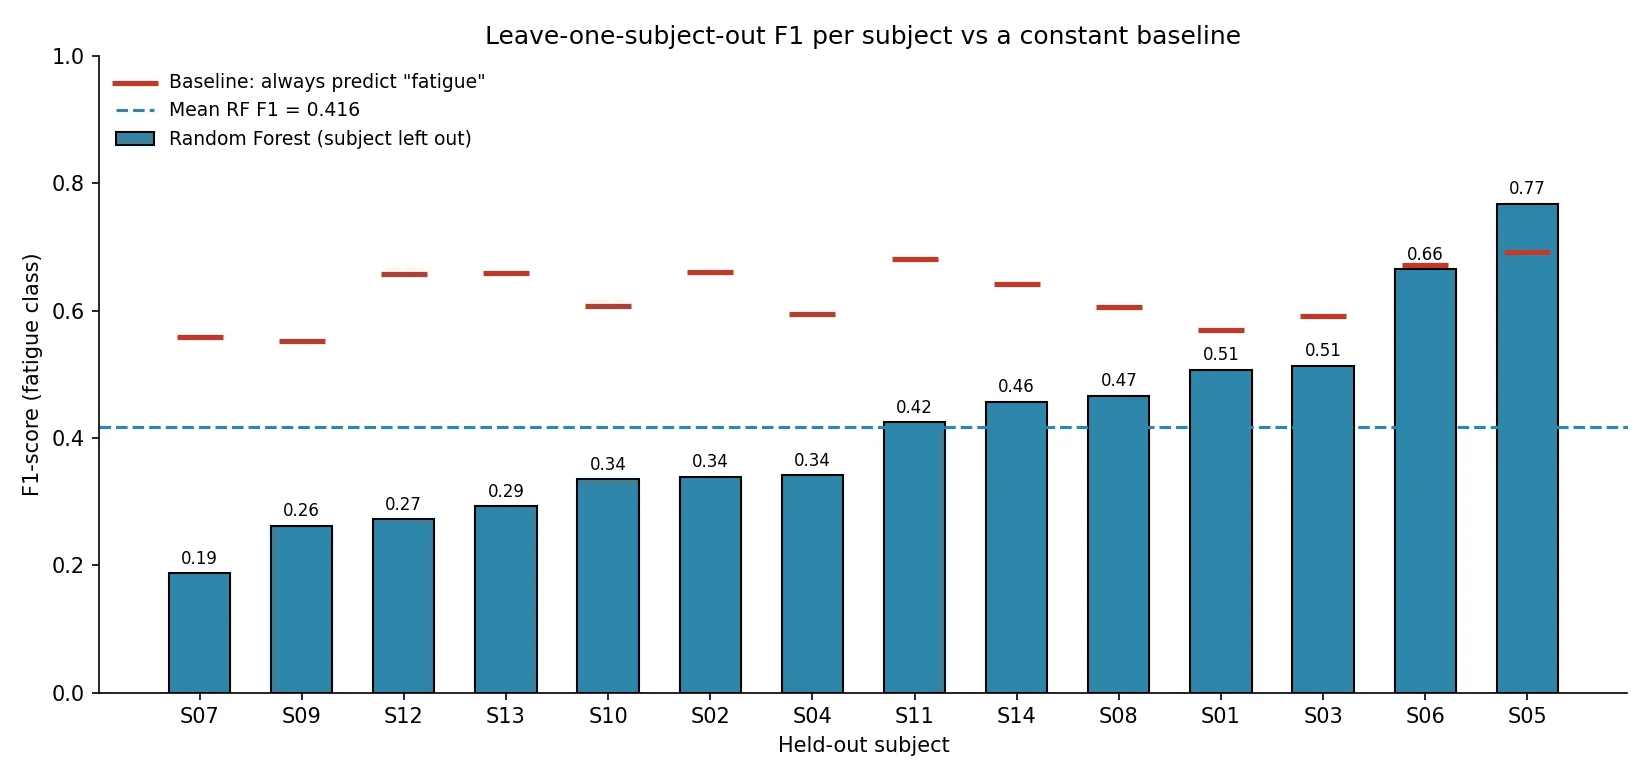
Bar chart of leave-one-subject-out F1 for 14 anonymised subjects, ranging from 0.19 to 0.77 with a mean of 0.416. A red marker per subject shows the score of always predicting fatigue, around 0.55 to 0.69; the model beats it for only one subject.
completed

EMG Muscle Fatigue Classification

Can surface EMG detect muscle fatigue in someone the model has never seen? 9,540 signal windows from 14 people, leave-one-subject-out testing, and an honest answer: not yet.
  • 9,540 windows, 14 subjects
  • Leave-one-subject-out
  • Mean F1 0.416 vs baseline 0.625

Python · SciPy · scikit-learn · pandas · matplotlib · SpikerTools

  • #health-tech
  • #signal-processing
  • #machine-learning